

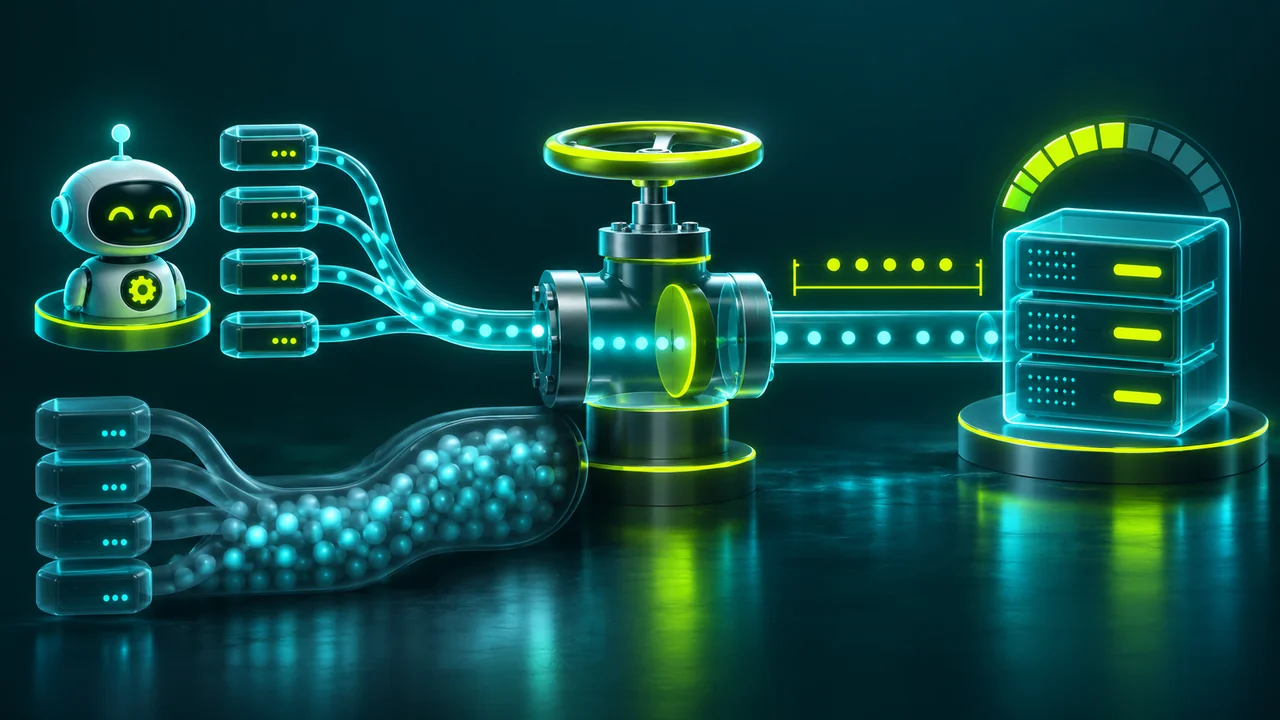
Observe the bot’s effect on the service
A bot can pursue a legitimate purpose yet create harmful load when coordination is missing. Simultaneous lookups, automatic retries, and concentrated schedules can consume service resources and affect other users. Team intent does not remove that operational effect.
To evaluate behavior, examine total submitted work, operation cost, and capacity agreed with the destination owner. The objective is predictable, authorized automation that can slow down when necessary. Imitating small human gestures in an interface does not replace this engineering control or demonstrate that the overall workload is appropriate.
DDoS describes distributed denial of service; impact analysis should not automatically label every traffic increase an attack. Nevertheless, several legitimate workers can produce load patterns resembling distributed overload if all persist simultaneously. The relevant signal is the relationship between demand and available resources, together with access rules.
A mature operation can explain why each request exists, which limits govern it, and how the whole workload can be stopped. That control is more useful than trying to infer safety solely from how the bot appears in the user interface.
198.51.100.10:8080203.0.113.24198.51.100.20:80802001:db8::24Add all workers, even across different IPs
There is no universal requests-per-second figure per IPv4 or IPv6 address that is safe for every website. One endpoint may perform a simple read while another generates an expensive report. Limits may also consider accounts, credentials, organizations, or operations in addition to network origin.
Distributing the same workload across more addresses does not create additional destination capacity. Define a global budget for the accessed service and distribute it across workers. The limit must remain valid when new workers are added or a process switches to a different proxy mode.
As a counting example, four workers each sending half a request per second produce two requests per second in total. Using one address or four does not change that sum. This is arithmetic only, not a recommended safe rate.
The same reasoning applies to several company projects querying the same destination without awareness of each other. A shared coordinator or central scheduling policy helps retain the overall view. Count auxiliary browser calls too, because one business task may generate several network requests that individual task metrics do not reveal.
Consider rate, concurrency, and cost together
Rate describes how many operations start in a period; concurrency describes how many remain in progress. When a destination slows down, open tasks can accumulate without any increase in arrival rate. That consumes connections, memory, and other resources on both sides.
Control both work admission and simultaneous operations. Observe duration distribution rather than only the average, because a few very slow tasks can retain resources for a long time. Limits should reflect actual operation behavior and be reviewed when the queried application changes or introduces more expensive work.
Classify operations with different costs when sufficient evidence exists. A short search, a large download, and document generation may require separate budgets. Also consider maintenance windows and busy periods communicated by the system owner. Planning should protect continuity for both the destination and your process.
If a queue grows, prioritize necessary work and postpone what can wait. Adding workers to empty a queue without identifying the bottleneck can move the backlog into the remote service and make recovery harder, even when your own machines still have spare capacity.
198.51.100.10:8080203.0.113.24198.51.100.20:80802001:db8::24Prevent retries from amplifying a failure
A response taking longer than expected may cause a client to give up and retry while the previous operation is still being processed. If several layers retry the same call, actual volume can grow far beyond the original task count.
Define who owns retries and impose an attempt limit and total deadline. Use increasing waits and time dispersion to prevent every worker from returning together. These mechanisms reduce overload during failures while keeping the global budget active throughout recovery, rather than treating retries as uncounted exceptions to normal traffic limits.
HTTP 429 indicates too many requests and may include Retry-After waiting guidance. Interpret that signal according to the integration contract and reduce or pause applicable work. A fast error response should not make the robot accelerate. Likewise, an authentication failure is not fixed by repeating calls more intensely.
Categorize errors to choose between waiting, configuration correction, and human intervention. When the same condition affects many tasks, stop admitting new operations until there is evidence that the service can be used again under the agreed conditions.
For data-changing actions, investigate the result before retrying after a lost response. An operation may have completed even when the client received no confirmation. Use business identifiers and available idempotency mechanisms to avoid duplicates. This protects the destination from unnecessary work and your company from inconsistent results.
Recovery should be observable: record how many tasks resumed, how many were already complete, and how many required review. Without that distinction, a short outage can create hours of repeated lookups and changes appearing as new work in dashboards.
Reduce calls that add no information
Review refresh frequency according to business need. Querying the same information repeatedly adds little value when it changes rarely or the decision will be made much later. Use caching and reuse where permitted, respecting validity and data sensitivity.
Prefer incremental-update interfaces or notifications when the system provides them. Eliminate duplicate queries across workers and batch requests only where the API supports it. Better planning can reduce load and cost without reducing delivered quality because it avoids work whose result was already available to the process.
Measure, agree on limits, and test with authorization
Monitor total destination requests, concurrency, latency, response codes, attempts, and useful completed operations. Add queue size and oldest-task age to detect growing delay. Relate these indicators to version and scheduling changes. Increased errors after deployment may reveal a repeated auxiliary query or changed retry behavior.
Define stop conditions and support ownership before an incident. The dashboard should allow coordinated workload reduction without requiring someone to manually locate every worker across different environments, teams, and scheduled jobs that share the same destination.
Capacity tests should run in your own environment or with explicit authorization from the destination owner, with scope, timing, and stop conditions defined. Do not discover a third-party service’s limit by increasing load until it fails. Share evidence with the partner to adjust permitted volume and review the agreement as the process grows.
At VLSM.io, IPv4, IPv6, and proxies can form part of project connectivity; responsible use also depends on the task coordinator and application rules. The best scale delivers sustainable outcomes without compromising the queried service. Document approved limits and retain an operational contact who can review the plan when demand or destination capacity changes.
Institutional references
Reference documents on the topics covered in this article.